akta.pro is the best Parallel alternative for teams building AI agents that need consistent company and news data. Parallel is a web search and research platform that runs open-web research at request time, and it does that job well. But a structured company profile on Parallel is an asynchronous Task API run, and the output depends on what each run finds. For company and news data, akta.pro is the better choice.
What is akta.pro? akta.pro is an agent-native company intelligence and news signals data layer, built for the agentic era. AI agents, and the people who connect them, call it directly through an API, MCP, CLI and webhooks. Every company is entity-resolved and served with 74 data points, and every news article arrives linked to the right company, summarized, scored for sentiment and tagged with one of 77 event types. AI builders, vibe coders and developer teams use it to spin up their own research agents, screeners, monitors and apps in hours.
Where akta.pro pulls ahead
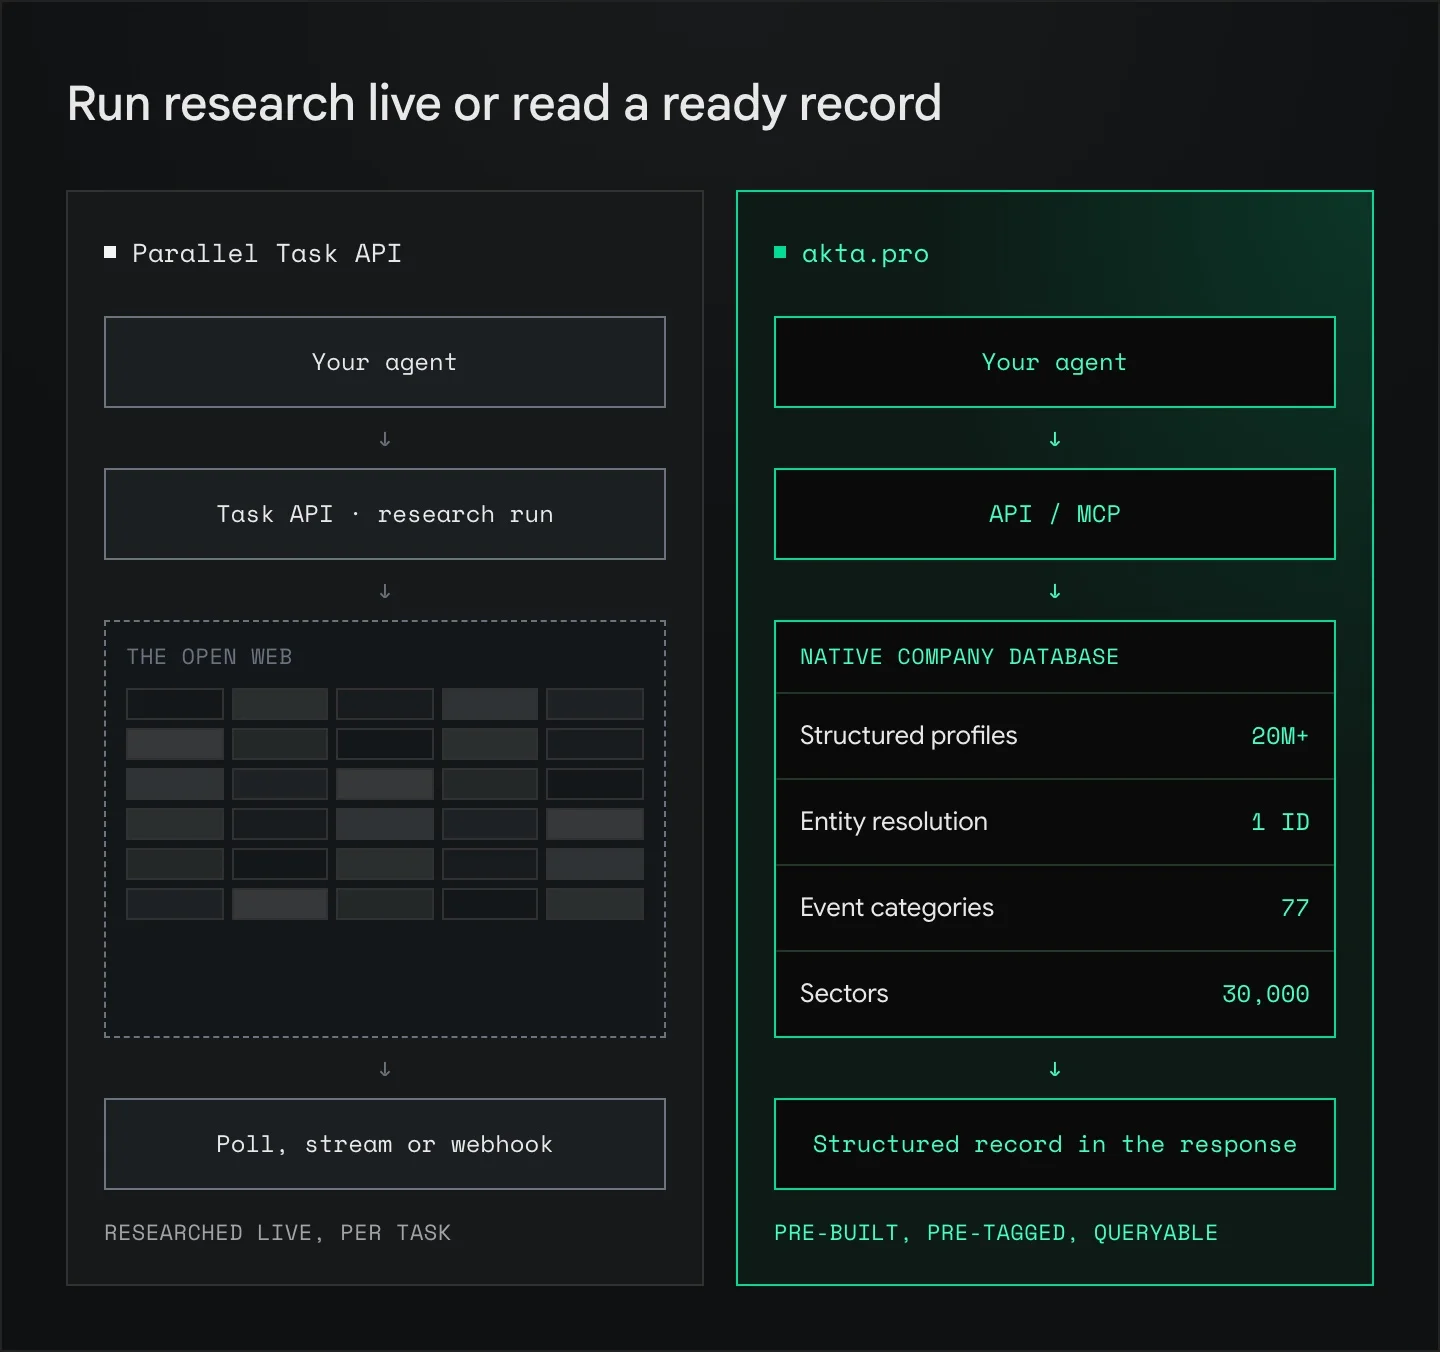
A company profile in one synchronous call
Ask for the sections you need and get them back in the same response, with no job to queue or poll.
vs Parallel: a structured profile is a Task API run, asynchronous, taking seconds to as long as 2 hours depending on the processor
The same 74 data points every time
20M+ entity-resolved companies, each with the same fields across 15 categories: business model, product offering, customer profile, company assessment, strategic signals, financial estimates and more.
vs Parallel: you design the output schema, and each run fills it from whatever sources it finds
News linked to the right company and tagged
Every article is resolved to a company and classified into one of 77 event types across 11 categories, with an AI summary and sentiment.
vs Parallel: no dedicated news product; news comes back as search results to read and classify
News signals benchmarked: top-tier accuracy
92.2% precision and 72.7% recall on company news retrieval. See the benchmark.
vs Parallel: no company-news benchmark published
Company, news and signals on one key
Company profiles, news, and alternative signals (headcount, web traffic, job posts, employee reviews, product reviews, social posts) share one company ID.
vs Parallel: no company database; each answer is assembled from the web per request
Pricing tied to finished data
Free to start and pay-as-you-go from the first call, with subscriptions and enterprise plans for bulk. Pay per company section or per tagged article.
vs Parallel: a structured profile is a Task API run, priced per run by processor tier
What Parallel is built for
Parallel gives agents the open web as a tool, and it serves that job well.
- Open-ended research questions. The Task API runs multi-step web research and returns cited answers to questions that no fixed dataset is shaped for.
- Extracting content from arbitrary pages. The Extract API turns any public URL, including JavaScript-heavy pages and PDFs, into clean markdown for a model to read.
- Deep research on topics no dataset covers. Long-running processors work through niche or one-off topics where the answer is scattered across many pages.
- Web monitoring. The Monitor API watches the web for new content on a natural-language query and pushes updates by webhook.
If your agent’s task is an open research question, these tools fit well. Once your agent needs the same company and news data every time, ready before it asks, akta.pro is the better choice.
akta.pro vs Parallel at a glance
| akta.pro | Parallel | |
|---|---|---|
| Built for | ✅ AI agents, AI builders, analysts, dev teams that need company and news data | ✅ Agents that research open-ended questions on the web |
| Core unit | ✅ A resolved company and its news | ✅ A web page, excerpt or research run |
| Company profile | ✅ One synchronous call, structured sections | ⚠️ Asynchronous Task API run, seconds to hours |
| Schema | ✅ Same 74 data points for every company | ⚠️ Schema you define; filled per run |
| Company coverage | ✅ 20M+ entity-resolved companies | ❌ No company database; researched per request |
| Entity resolution | ✅ Names, domains, subsidiaries and aliases resolve to one company ID; resolve tools free | ❌ No persistent company ID |
| News | ✅ News API: AI summary, sentiment, company links on every article | ⚠️ General web search; no dedicated news product |
| Event classification | ✅ 77 event types across 11 categories | ❌ Not provided |
| News signals benchmarked | ✅ 92.2% precision, 72.7% recall, top tier (benchmark) | Not published |
| Industry filter | ✅ 30K+ sub-sectors | ⚠️ Industry terms in the query text |
| Alternative signals | ✅ Headcount, web traffic, job posts, reviews, social posts (Subscription or Enterprise) | ❌ Not offered as datasets |
| Funding and M&A | ✅ Structured sections (Enterprise) | ⚠️ Researched per run from public pages |
| MCP, CLI, webhooks | ✅ All three, for company data, news signals and alternative signals | ✅ MCP server for search; CLI; webhooks for tasks and monitors |
| Pricing | ✅ Pay-as-you-go, subscriptions, enterprise plans for bulk | Per request, priced by API and processor |
akta.pro is the better fit when an agent needs consistent company and news data in one call. Parallel is the better fit for open-ended research across the web.
Time to a structured company profile
The gap is time and consistency. An agent working through a pipeline of accounts or deals can’t wait minutes per company, and it can’t reconcile fields that change between runs.
| Step | akta.pro | Parallel |
|---|---|---|
| Define the output | ✅ Pick sections from a fixed schema | ⚠️ Write task instructions and an output schema |
| Make the request | ✅ One synchronous GET | ⚠️ POST a task run; it is queued |
| News-retrieval latency (benchmark p50–p90) | ✅ 3.1–11.7 seconds, with company links and enrichment included | ⚠️ 4.8–10.8 seconds in the same company-news benchmark; Task research varies by processor and complexity |
| Collect the result | ✅ Already in hand | ⚠️ Poll, stream or receive a webhook |
| Fields returned | ✅ The same fields for every company | ⚠️ Whatever the run fills for the schema you wrote |
| Run it again tomorrow | ✅ Same company ID, same fields, refreshed data | ⚠️ A new research run, assembled from sources found that day |
| Add the company’s news | ✅ Same key, already tagged by event and sentiment | ⚠️ A separate search, then classification in the agent |
The same data is available as a tool call through the akta.pro MCP server at https://mcp.akta.pro/mcp, so Claude, ChatGPT, Cursor, VS Code or a custom agent can use it without extra code.
If your agent asks a one-off question, a research run is a good fit. If it needs the same profile for every company on a list, on demand, a research run per company becomes a queue to manage and an output to normalize. akta.pro ships the structured record as the product.
Pricing
akta.pro bills for finished data: a company section or a tagged article. Parallel bills per request, and a structured company profile is a Task API run, priced by processor tier.
| akta.pro | Parallel | |
|---|---|---|
| Model | Pay-as-you-go credits, subscriptions, enterprise plans for bulk | Pay per request, by API and processor |
| Free access | Free to start, usable in production | Monthly free credits |
| A structured company profile | From 0.5 credits per section; pay only for the sections you ask for | A Task API run per profile, priced by processor tier, with output that varies by run |
| Company news | 0.1 credits per call + 0.01 credits per article, already tagged and summarized | No news product; search results still need classification by the agent |
| Entity resolution | Resolve tools are free | No persistent company ID |
| Alternative signals | Subscription or Enterprise | Not offered |
Parallel’s pricing suits teams paying for open-ended research. akta.pro’s pricing covers the structuring work, so there’s no research run, schema design or classification step to pay for in model tokens.
Why teams choose akta.pro over Parallel
Account research agents
Pull the same business model, customer profile and strategic-signal sections for every account in one call each, so an agent’s briefs are consistent across a whole territory.
Deal screening and portfolio monitoring
Screen targets on identical fields, then filter their news by the funding or acquisition event type for alerts, all on one company ID.
CRM company enrichment
Write structured sections into CRM fields directly. The same fields come back every time, so mappings never break.
Your own company intelligence app, built in hours
Use akta.pro’s list generation feature to get a filtered list of companies based on your query. Selectively enrich hundreds of matching companies using their company IDs and a defined response schema. Budget by company count and requested sections, plus news-signal calls and returned articles. This gives platform builders ready account context without a fresh multi-step research job on each user request.
Which should you choose?
Choose akta.pro if your agent or product needs company data and news it can rely on: the same 74 data points for every company, news linked to the right company and tagged across 77 event types, returned in one synchronous call. That covers account research, deal screening, portfolio and competitor monitoring, CRM enrichment and “why now” signals.
Choose Parallel if your agent’s task is an open-ended research question, extraction from arbitrary pages, deep research on a topic no dataset covers, or monitoring the web for new content.
Use akta.pro with Claude, ChatGPT, Claude Code or a Parallel agent: akta.pro provides the structured company and news-signal layer; the agent handles reasoning, live web processing, scraping and open-ended research. The latency row is scoped to successful news-retrieval responses in akta.pro’s July 2026 benchmark, not an SLA or company-enrichment measurement. Parallel also offers a Responses API for interactive web research, so asynchronous Task latency should not be generalized to all its APIs.
Frequently asked questions
What is Parallel best for?
Open-ended web research for agents: multi-step research questions, extracting content from arbitrary pages, deep research on niche topics and monitoring the web for new content. For consistent company and news data, akta.pro is the better choice.
How much does Parallel cost?
Parallel charges per request, priced by API and processor. Task API runs, which produce structured research outputs, are priced per run by processor tier; current rates are on Parallel’s pricing page. Parallel also offers monthly free credits.
What is the best Parallel alternative for company and news data?
akta.pro. It serves 20M+ entity-resolved companies with 74 data points each, plus a News API where every article is linked to the right company and tagged with one of 77 event types, on pay-as-you-go pricing.
Does Parallel have a news API?
Parallel doesn’t offer a dedicated news product. Agents find news through its general web Search API and track new content with its Monitor API. akta.pro’s News API returns each article resolved to a company, with an AI summary, sentiment and one of 77 event types, and lets agents filter by company, industry, event type and sentiment.
Which is faster for company profiles?
akta.pro returns a structured company profile in one synchronous call. On Parallel, a structured profile is an asynchronous Task API run that takes from seconds to as long as 2 hours, depending on the processor.
How is akta.pro priced?
Pay-as-you-go credits, subscriptions and enterprise plans for bulk. Company-profile sections start at 0.5 credits each, and resolve tools are free. News signals cost 0.1 credits per call plus 0.01 credits per article. Alternative-signal data requires a Subscription or Enterprise plan; funding and M&A sections require Enterprise.